Home › AI-Crawler & llms.txt Census
✓ crawled 2026-10-02: robots.txt and llms.txt for the top 100,000 sites on the Tranco list · method · download the data
Which websites tell AI crawlers to stay out, and who has rolled out the welcome mat with an llms.txt file? On 2 October 2026 we fetched the robots.txt and llms.txt files of the 100,000 most popular websites (by the research-grade Tranco ranking) and checked, line by line, what each one says to 16 named AI agents. Then we did the same for the companies that sell proxies and scraping tools.
- sites checked 100,000
- readable robots.txt 57,847
- block GPTBot by name 8.9%
- publish llms.txt 11.5%
- scraping firms blocking AI 0 of 17
The headline numbers
- About 1 in 11 of the top 100,000 websites blocks OpenAI’s GPTBot by name. 8.9% of sites with a readable robots.txt (5,167 of 57,847) name GPTBot and shut it out of the whole site. That makes it the most-blocked AI crawler, just ahead of CCBot (Common Crawl) at 8.5%.
- The bigger the site, the more likely it blocks AI. Among the top 1,000 sites, 15.9% block GPTBot by name, compared with 8.9% across the top 100,000.
- Most sites that block AI training still let AI search in. 12.5% of sites block at least one major AI-training crawler by name. Of those, 61% still allow every AI search crawler we checked (OpenAI’s OAI-SearchBot, PerplexityBot and Claude-SearchBot).
- Only 3.0% block all seven big AI-training crawlers (GPTBot, ClaudeBot, CCBot, Google-Extended, Applebot-Extended, Bytespider and Meta’s meta-externalagent). Most blockers pick and choose.
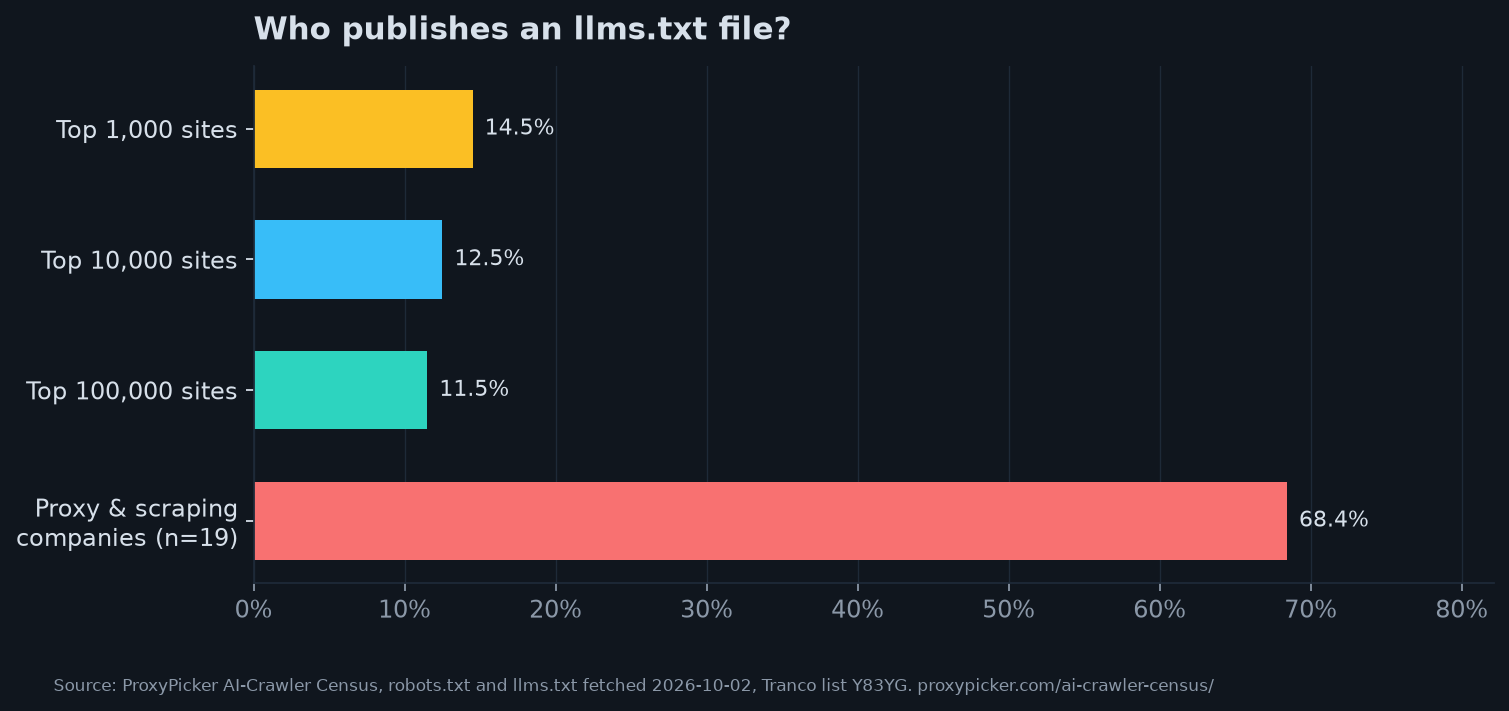
- llms.txt is still niche: 11.5% of reachable sites publish one (8,617 of 75,069). Among the top 1,000 it’s 14.5%.
- The companies that sell scraping don’t block AI scrapers. 0 of the 17 proxy and scraping-tool companies with a readable robots.txt block any AI crawler. 4 mention AI bots by name, and all of them do it to let the bots in. 13 of 19 publish an llms.txt, far above the web average.
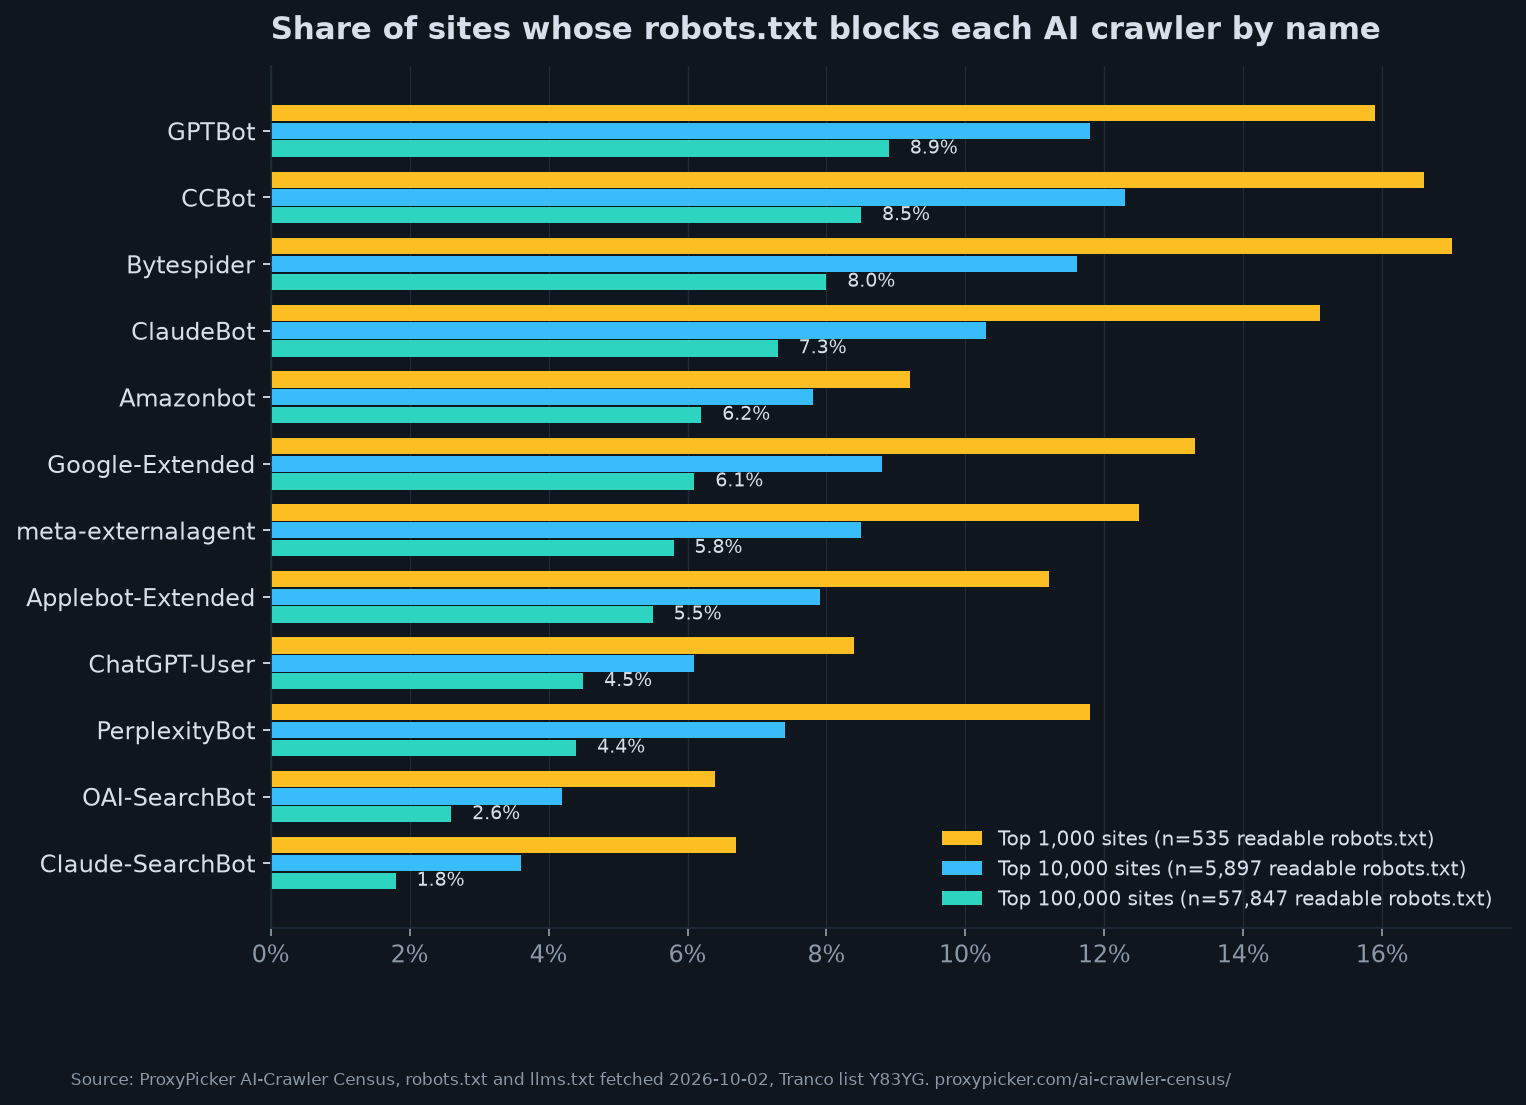
AI crawler by AI crawler
The “by name” column counts sites that name the crawler and disallow the whole site. The “including catch-all” column also counts sites whose general User-agent: * rule blocks everything, which stops every crawler, not just AI.
| Crawler | Operator | Used for | Blocked by name, top 1,000 | Blocked by name, top 10,000 | Blocked by name, top 100,000 | Incl. catch-all, top 100,000 |
|---|---|---|---|---|---|---|
GPTBot | OpenAI | training | 15.9% | 11.8% | 8.9% | 12.5% |
CCBot | Common Crawl | training | 16.6% | 12.3% | 8.5% | 12.2% |
Bytespider | ByteDance | training | 17.0% | 11.6% | 8.0% | 11.7% |
ClaudeBot | Anthropic | training | 15.1% | 10.3% | 7.3% | 11.0% |
Amazonbot | Amazon | mixed | 9.2% | 7.8% | 6.2% | 9.9% |
Google-Extended | training (token) | 13.3% | 8.8% | 6.1% | 9.6% | |
meta-externalagent | Meta | training | 12.5% | 8.5% | 5.8% | 9.4% |
Applebot-Extended | Apple | training (token) | 11.2% | 7.9% | 5.5% | 9.3% |
anthropic-ai | Anthropic | legacy token | 8.6% | 7.8% | 5.5% | 9.3% |
cohere-ai | Cohere | legacy token | 10.7% | 7.8% | 4.8% | 8.7% |
ChatGPT-User | OpenAI | user action | 8.4% | 6.1% | 4.5% | 8.1% |
PerplexityBot | Perplexity | search | 11.8% | 7.4% | 4.4% | 8.1% |
OAI-SearchBot | OpenAI | search | 6.4% | 4.2% | 2.6% | 6.3% |
Claude-SearchBot | Anthropic | search | 6.7% | 3.6% | 1.8% | 5.6% |
Perplexity-User | Perplexity | user action | 7.5% | 4.0% | 1.8% | 5.6% |
Claude-User | Anthropic | user action | 7.7% | 3.7% | 1.7% | 5.6% |
Training versus search
| Share of sites with a readable robots.txt that… | Top 1,000 | Top 10,000 | Top 100,000 |
|---|---|---|---|
| name at least one AI agent | 39.8% | 30.8% | 22.5% |
| block at least one AI agent by name | 28.6% | 20.4% | 15.4% |
| block at least one of the 7 training crawlers | 23.9% | 16.8% | 12.5% |
| block all 7 training crawlers | 3.9% | 3.9% | 3.0% |
| block training but allow AI search | 10.7% | 9.1% | 7.6% |
block every crawler with User-agent: * | 8.2% | 4.1% | 4.0% |
| Sites with a readable robots.txt (n) | 535 | 5,897 | 57,847 |
llms.txt: who has one?
llms.txt is a proposed plain-text file that gives AI tools a map of a site. It’s the opposite of a block: an invitation. We counted a site as having one if /llms.txt returned a real text file (not an HTML error page or a redirect to the homepage). Most real ones (7,687 of 8,617) start with a Markdown # Title line, as the proposal suggests. The median file is 6 KB.
Sidebar: do scraping companies block scrapers?
We ran the same checks on 19 companies that sell residential proxies or scraping APIs. Short answer: not in robots.txt. 0 of the 17 with a readable file block any AI crawler, and none block all crawlers. Several go out of their way to invite AI in:
- Bright Data lists GPTBot, ChatGPT-User, ClaudeBot, Google-Extended, PerplexityBot, Applebot-Extended and CCBot one by one with
Allow: /, and adds aContent-Signal: search=yes, ai-input=yes, ai-train=yesline. - Rayobyte names 14 AI agents, mostly AI search and assistant bots (OAI-SearchBot, ChatGPT-User, Claude-SearchBot, PerplexityBot and others), and blocks none of them. ScraperAPI has a section headed “AI AGENT FAST TRACK” that points GPTBot, Google-Extended, ClaudeBot and PerplexityBot to its llms.txt. Zyte gives GPTBot, Google-Extended, CCBot, ChatGPT-User and PerplexityBot their own
Allow: /section with the same rules as everyone else. - 13 of 19 publish an llms.txt, compared with 11.5% of the top 100,000 websites.
Robots.txt is only a polite request, though. What do these sites do to bots at the door? We checked the cookies recorded in HTTP Archive’s September 2026 crawl for the 17 vendor domains in that crawl (netnut.io excluded), counting a cookie only if it was set for the vendor’s own domain. On their main websites, only Bright Data and ScraperAPI set Cloudflare’s __cf_bm bot cookie, and Proxy-Cheap, ProxyEmpire and Scrape.do set Cloudflare’s cf_clearance challenge cookie. SOAX, Webshare, Proxy-Seller, Proxy-Cheap, NodeMaven and Zyte set __cf_bm only on a docs, help, support or login subdomain, which are often run by outside help-desk or login services. For the other 7 (Oxylabs, Decodo, IPRoyal, DataImpulse, Rayobyte, Apify and ScrapingBee), every Cloudflare bot cookie we saw came from a third-party embed such as HubSpot, LinkedIn, X or G2 widgets. 8 use a CAPTCHA somewhere on their sites (reCAPTCHA, Cloudflare Turnstile or GeeTest), mostly on sign-up, dashboard or status pages. Three (DataImpulse, Oxylabs and Rayobyte) also run ClickCease, which screens ad clicks for bots. In other words: AI crawlers are welcome to read the marketing pages, and some of the account pages sit behind bot screening.
| Company | robots.txt | AI agents named | Blocks AI? | llms.txt | Bot screening seen (HTTP Archive, Sep 2026) |
|---|---|---|---|---|---|
| brightdata.com | readable | 7 | no | yes | Cloudflare bot cookie (main site), GeeTest |
| oxylabs.io | readable | 0 | no | yes | ClickCease |
| decodo.com | readable | 0 | no | yes | none detected |
| iproyal.com | readable | 0 | no | yes | reCAPTCHA |
| soax.com | readable | 0 | no | no (404) | Cloudflare bot cookie (subdomain only) |
| webshare.io | readable | 0 | no | yes | Cloudflare bot cookie (subdomain only), reCAPTCHA |
| dataimpulse.com | readable | 0 | no | yes | ClickCease, Cloudflare Turnstile |
| rayobyte.com | readable | 14 | no | yes | ClickCease, reCAPTCHA |
| proxy-seller.com | readable | 0 | no | yes | Cloudflare bot cookie (subdomain only) |
| proxy-cheap.com | readable | 0 | no | no (404) | Cloudflare challenge cookie (main site) |
| nodemaven.com | readable | 0 | no | yes | Cloudflare bot cookie (subdomain only) |
| proxyempire.io | readable | 0 | no | no (404) | Cloudflare challenge cookie (main site) |
| stormproxies.com | readable | 0 | no | no (404) | not in crawl |
| netnut.io | not a robots file* | – | n/a | no | none detected |
| apify.com | readable | 0 | no | yes | reCAPTCHA |
| scrape.do | not a robots file* | – | n/a | no | Cloudflare challenge cookie (main site) |
| scraperapi.com | readable | 4 | no | yes | Cloudflare bot cookie (main site), Cloudflare Turnstile |
| scrapingbee.com | readable | 0 | no | yes | reCAPTCHA |
| zyte.com | readable | 5 | no | yes | Cloudflare bot cookie (subdomain only) |
* netnut.io currently serves a law-enforcement seizure notice in place of its site, and scrape.do returns an HTML page at /robots.txt. CAPTCHA and ClickCease detections come from HTTP Archive’s Wappalyzer rules. “Cloudflare bot cookie” means a __cf_bm cookie set for the vendor’s own domain (Cloudflare sets it when Bot Fight Mode or Bot Management is on); “challenge cookie” means cf_clearance. Neither tells us which Cloudflare plan or settings a site uses. Corrected 2 October 2026: an earlier version counted __cf_bm cookies set by third-party embeds and said all 17 vendors set Cloudflare’s bot cookie. See the Anti-Bot Census for why that overcounts.
Methodology (crawl run 2026-10-02)
- Sites: the top 100,000 registrable domains of Tranco list Y83YG (generated 1 October 2026, averaging 2 September–1 October 2026). Tranco combines several popularity sources into a ranking designed for research. It ranks domains, not websites, so it includes infrastructure domains (CDNs, ad servers, APIs) that have no website.
- What we fetched: only
https://DOMAIN/robots.txtandhttps://DOMAIN/llms.txt(falling back towww.if the bare domain didn’t connect), following up to five redirects. Nothing else on any site was requested. - Politeness: our crawler identified itself as
ProxyPickerResearchBot/1.0 (+https://proxypicker.com/methodology/), opened no more than two connections to any host, and gave up after 20 seconds. Connection failures got one slower retry (one connection per host, 30-second timeout). - Readable robots.txt: a 200 response that is a text file at a /robots.txt path. Of the top 100,000: 57,847 readable; 9,286 returned 404/410 (no robots.txt, so everything is allowed); 8,006 returned another 4xx error, usually 403 (refused); 5,165 returned an HTML page or redirected away; 19,531 didn’t answer, had no web server, or returned a 5xx error. Percentages use readable robots.txt files as the base.
- “Blocks”: we parsed each file with Protego (the robots.txt parser used by Scrapy) and asked whether the crawler may fetch both the homepage and a typical article URL. “By name” also requires a
User-agentline naming that crawler, so general*blocks don’t count as AI blocking. Partial blocks (only some folders) don’t count as blocks. - Agent list: 16 headline agents, with purposes taken from each operator’s documentation, plus the 180 agents in the community ai.robots.txt list (commit 987266f, 26 September 2026) for the “names any AI agent” figures.
- Vendor technology: HTTP Archive’s public crawl of 1 September 2026 (Wappalyzer detections for CAPTCHAs and ClickCease; the crawl’s recorded cookies for Cloudflare, counting only cookies set for the vendor’s own domain), queried in BigQuery for the vendor domains only.
Limitations
- robots.txt is a request, not a wall. Many sites block AI bots at the network level (firewall or CDN rules) without mentioning them in robots.txt. This census measures what sites ask, not what they enforce.
- Some sites refuse unknown bots outright. 8,006 returned an error such as 403 to our polite, identified request, and a site may show different robots.txt rules to different user agents.
- Our crawler ran from a single network location. 18,507 domains still failed to connect after a retry; many of these are infrastructure domains with no website, but some are real sites we simply couldn’t reach.
- A single day’s snapshot. Robots files change; we plan to re-run this census every month.
Cloudflare publishes its own network-level view of AI-crawler traffic on Cloudflare Radar. That measures something different (traffic, not robots.txt rules), and we don’t use its figures here.
Download the data
- Per-site results (CSV): rank, domain, robots.txt status and state, AI agents blocked by name, training/search flags, llms.txt status and size. No file contents.
- Summary by popularity bucket (CSV)
- Proxy & scraping company sidebar (CSV)
Free to use with attribution. Please cite the crawl date.
Cite or embed
Suggested citation: ProxyPicker (2026). “AI-Crawler & llms.txt Census: robots.txt rules of the top 100,000 websites.” Crawled 2 October 2026. https://proxypicker.com/ai-crawler-census/
Embed the chart:
<a href="https://proxypicker.com/ai-crawler-census/"><img src="https://proxypicker.com/wp-content/uploads/2026/10/proxypicker-census-blocks-by-agent-2026-10.png" alt="Share of top websites blocking each AI crawler in robots.txt (ProxyPicker AI-Crawler Census)" width="800" /></a><br />Source: <a href="https://proxypicker.com/ai-crawler-census/">ProxyPicker AI-Crawler Census</a> (crawled 2026-10-02)Site ranking: Le Pochat et al., “Tranco: A Research-Oriented Top Sites Ranking Hardened Against Manipulation,” NDSS 2019. List ID Y83YG.
Related: The Price of a Gigabyte · Proxy Price Index · our methodology · Where Bot Traffic Comes From (honeypot attacks by source country).
Press & data requests: email [email protected] for interviews, the raw data behind this page, or corrections. See also our contact page.